Kafka Interview Guide: Architecture, Consumers, Partitions & Exactly-Once Semantics
From Broker Internals and ISR Replication to Rebalancing Protocols and Transactional Exactly-Once Pipelines
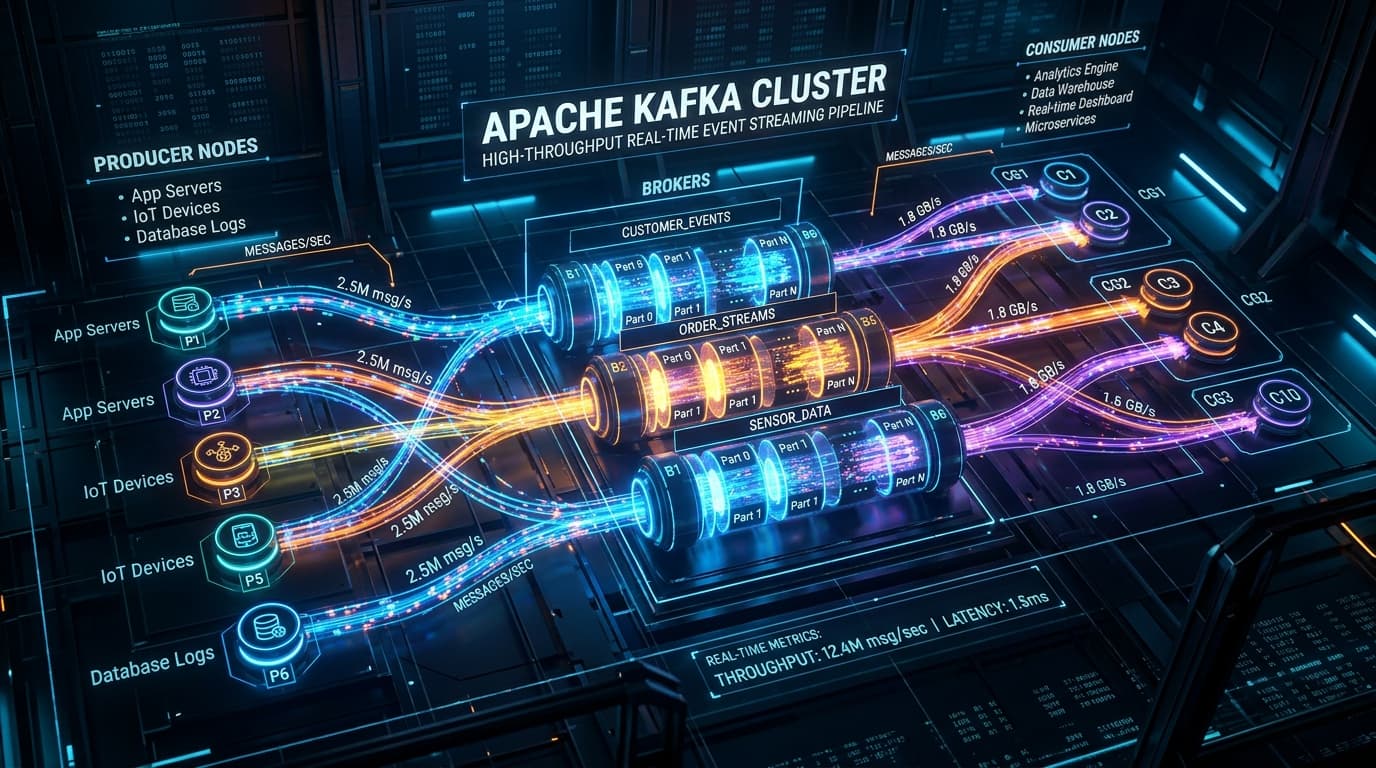
What You Must Master to Clear This Track
- Understand that Kafka guarantees ordering only within a partition, not across a topic, and design partition keys around causally related events.
- Master the acks / min.insync.replicas trade-off and know precisely why acks=1 alone is not a durability guarantee.
- Explain exactly-once semantics as the combination of the idempotent producer, Kafka transactions, and the read_committed consumer isolation level, not a single config flag.
- Know cooperative-sticky rebalancing (KIP-429) and static group membership as the standard fixes for rebalance storms in large consumer groups.
- Be fluent in retention versus log compaction, and in monitoring consumer lag and under-replicated partitions as production health signals.
Step-by-Step Study Plan
Follow this sequential roadmap designed to take you from core foundations to advanced architecture and mock interviews.
Replication, ISR & Leader Election Foundations
Brokers, topics, partitions as ordered logs, replication factor, In-Sync Replica sets, controller-driven leader election, and the KRaft metadata quorum.
- •Explain how a topic's partitions are distributed and replicated across brokers and racks.
- •Trace exactly what happens to the ISR when a follower falls behind replica.lag.time.max.ms.
- •Understand how the KRaft controller quorum replaces ZooKeeper for metadata and leader election.
- •Draw out replica placement for a 3-broker cluster with replication.factor=3 and broker.rack set per AZ.
- •Study how min.insync.replicas interacts with acks to define your durability floor.
Acks, Idempotence, Rebalancing & Exactly-Once Transactions
Producer acks and partitioning strategy, idempotent producers, consumer group rebalancing protocols, offset management, and transactional exactly-once processing.
- •Configure an idempotent, transactional producer and reason about producer fencing.
- •Compare eager (stop-the-world) rebalancing against cooperative-sticky (KIP-429) rebalancing.
- •Trace a full consume-transform-produce loop under exactly_once_v2 semantics.
- •Practice explaining a rebalance storm caused by a short session.timeout.ms and how static membership fixes it.
- •Write a small producer-consumer transaction that commits offsets and output records atomically.
Stream Processing Topologies & Operational Excellence
KStream/KTable semantics, stateful aggregations with changelog-backed state stores, ksqlDB continuous queries, retention vs compaction, and monitoring consumer lag.
- •Build a Kafka Streams topology with a stateful groupBy/aggregate step under exactly_once_v2.
- •Write an equivalent continuous aggregation in ksqlDB and compare developer ergonomics.
- •Monitor consumer lag and under-replicated partitions using CLI tools and JMX-based dashboards.
- •Tune retention.ms/retention.bytes for event topics and cleanup.policy=compact for changelog-style topics.
- •Set up alerting on ISR shrink and under-replicated partition count as leading failure indicators.
1. Broker, Topic & Partition Architecture: Replication and Leader Election
Every Kafka interview starts here: a topic is a logical name for one or more ordered, append-only partitions, and durability comes entirely from how those partitions are replicated across brokers.
Kafka only guarantees strict FIFO ordering within a single partition, never across an entire topic. Records with the same key always land on the same partition, which is how causally related events (e.g. all events for one order) stay ordered.
Each partition has one leader and N-1 followers. The ISR is the subset of replicas that have fully caught up within replica.lag.time.max.ms. Only ISR members are eligible to become the next leader without data loss.
When a leader broker dies, the controller promotes an ISR replica to leader. If unclean.leader.election.enable=true, a non-ISR replica can be promoted to preserve availability, at the cost of silently losing unreplicated records.
Modern Kafka (3.x+ in KRaft mode) replaces the ZooKeeper-based controller with a self-managed Raft quorum of controller nodes that stores topic/partition metadata and drives leader elections, removing the external ZooKeeper dependency entirely.
How a single record travels from producer-side partitioning through leader replication to consumer group processing.
- Set broker.rack per availability zone so replica placement spreads across failure domains, not just across brokers in the same rack.
- Treat min.insync.replicas as your real durability contract; acks=all is meaningless for durability if min.insync.replicas is left at 1.
- Assuming replication.factor=3 alone protects against data loss while min.insync.replicas is still set to 1.
- Enabling unclean.leader.election.enable=true on financial or audit-sensitive topics purely to avoid short unavailability windows.
2. Producers: Acks, Idempotence, Partitioning & Exactly-Once Transactions
Producer configuration is where most real-world data loss and duplication bugs originate. Interviewers expect you to reason precisely about what each acks value and the idempotent/transactional producer actually guarantee.
acks=0 fires and forgets with no wait (highest throughput, highest loss risk). acks=1 waits only for the leader's local write (loses data if the leader dies before followers replicate). acks=all waits for every ISR member up to min.insync.replicas.
enable.idempotence=true assigns each producer a Producer ID (PID) and per-partition sequence numbers. The broker deduplicates retried sends with the same PID+sequence, eliminating duplicate writes caused by network retries.
The default partitioner hashes the record key (murmur2) modulo partition count for keyed records, and uses a sticky partitioner (batches multiple null-key records onto the same partition before switching) for unkeyed records to improve batching efficiency.
A transactional.id lets a producer begin/commit/abort atomic transactions spanning multiple partitions and topics, including committing consumer offsets in the same transaction via sendOffsetsToTransaction, enabling an exactly-once consume-transform-produce loop.
Properties props = new Properties();
  props.put(ProducerConfig.BOOTSTRAP_SERVERS_CONFIG, "broker1:9092,broker2:9092");
  props.put(ProducerConfig.ACKS_CONFIG, "all");
  props.put(ProducerConfig.ENABLE_IDEMPOTENCE_CONFIG, true);
  props.put(ProducerConfig.TRANSACTIONAL_ID_CONFIG, "payments-processor-1");
  props.put(ProducerConfig.KEY_SERIALIZER_CLASS_CONFIG, StringSerializer.class.getName());
  props.put(ProducerConfig.VALUE_SERIALIZER_CLASS_CONFIG, StringSerializer.class.getName());

  KafkaProducer<String, String> producer = new KafkaProducer<>(props);
  producer.initTransactions(); // Fences any older "zombie" producer with the same transactional.id

  try {
      producer.beginTransaction();
      producer.send(new ProducerRecord<>("payment-events", orderId, payload));

      // Ties the consumer's offset commit to THIS producer transaction for exactly-once semantics
      producer.sendOffsetsToTransaction(offsetsToCommit, consumerGroupMetadata);

      producer.commitTransaction();
  } catch (ProducerFencedException | OutOfOrderSequenceException | AuthorizationException fatal) {
      producer.close(); // Non-recoverable: another instance has taken over this transactional.id
  } catch (KafkaException retriable) {
      producer.abortTransaction();
}- Tune linger.ms (a few milliseconds) alongside batch.size to trade a small amount of latency for dramatically better throughput and compression ratios.
- Use compression.type=lz4 or zstd on high-volume topics; the CPU cost is almost always cheaper than the network and disk I/O it saves.
- Reusing the same transactional.id across multiple concurrently running producer instances, which triggers ProducerFencedException.
- Enabling idempotence but forgetting that retries.max and max.in.flight.requests.per.connection <= 5 are required for ordering guarantees to hold.
3. Consumer Groups, Rebalancing Protocols & Kafka Streams / ksqlDB
Consumer-side questions probe whether you understand how Kafka achieves parallelism safely, and whether you can reason about the stream-processing layer built on top of the consumer API.
Each partition in a topic is assigned to exactly one consumer instance within a group; multiple groups can independently consume the same topic. Scaling consumers beyond the partition count leaves the extra consumers permanently idle.
The legacy eager protocol revokes ALL partitions from ALL members before reassigning (a stop-the-world pause). Cooperative-sticky rebalancing only reassigns the specific partitions that must move, letting unaffected consumers keep processing.
Setting group.instance.id gives a consumer a stable identity across restarts, so a brief restart (e.g. a rolling deploy) doesn't trigger a full group rebalance -- the member simply rejoins with its old assignment intact.
Kafka Streams models topics as KStream (append-only event log) or KTable (compacted, latest-value-per-key changelog). Stateful operations persist to RocksDB-backed state stores that are themselves replicated via internal changelog topics. ksqlDB layers a continuous SQL query engine on top of the same Streams engine.
StreamsBuilder builder = new StreamsBuilder();

  KStream<String, Order> orders = builder.stream(
      "orders-topic",
      Consumed.with(Serdes.String(), orderSerde));

  KTable<String, Long> orderCountsByCustomer = orders
      .groupBy((key, order) -> order.getCustomerId(), Grouped.with(Serdes.String(), orderSerde))
      .count(Materialized.as("customer-order-counts-store")); // Backed by a changelog topic

  orderCountsByCustomer.toStream()
      .to("customer-order-counts", Produced.with(Serdes.String(), Serdes.Long()));

  Properties props = new Properties();
  props.put(StreamsConfig.APPLICATION_ID_CONFIG, "order-aggregator-app");
  props.put(StreamsConfig.BOOTSTRAP_SERVERS_CONFIG, "broker1:9092,broker2:9092");
  props.put(StreamsConfig.PROCESSING_GUARANTEE_CONFIG, StreamsConfig.EXACTLY_ONCE_V2);

  KafkaStreams streams = new KafkaStreams(builder.build(), props);
streams.start();- Prefer the cooperative-sticky assignor (partition.assignment.strategy) for any consumer group larger than a handful of instances.
- Use ksqlDB for quick operational dashboards and ad-hoc continuous queries; fall back to hand-written Kafka Streams for complex joins, custom processors, or tight latency SLAs.
- Setting session.timeout.ms too low relative to actual GC pause or processing time, causing consumers to be falsely marked dead and triggering avoidable rebalances.
- Confusing max.poll.interval.ms (time budget between poll() calls before the consumer is considered dead) with session.timeout.ms (heartbeat-based liveness detection).
4. Operations: Retention, Compaction & Monitoring Consumer Lag
Senior candidates are expected to run Kafka in production, not just write producers and consumers. Retention strategy and lag monitoring are the two operational topics interviewers probe most.
retention.ms (default 7 days) and retention.bytes control how long/how much data a partition keeps before deleting the oldest segments, regardless of whether consumers have read it.
cleanup.policy=compact retains only the latest value per key forever (used for changelog topics, CDC feeds, and KTable-backed state). Deleting a key requires writing a null-value tombstone, which is itself purged after delete.retention.ms.
Lag = partition log-end-offset minus the consumer group's last committed offset. Track it via kafka-consumer-groups.sh --describe, Burrow, or a JMX exporter feeding Prometheus/Grafana, and alert on lag growth rate, not just an absolute threshold.
More partitions increase parallelism but also increase rebalance cost, open file handle count, and replication overhead. A rising under-replicated-partitions metric is an early signal of broker or network stress before an outage occurs.
- Size partitions using target-partition-throughput / per-partition-throughput as a starting point, then leave headroom to scale consumers without a topic re-partition.
- Alert on under-replicated partitions and ISR-shrink events as leading indicators; by the time consumer lag spikes, the underlying broker issue is often already hours old.
- Applying cleanup.policy=compact to a plain event-log topic, which silently drops historical events you actually needed for replay or auditing.
- Over-partitioning topics 'for future scale,' which slows controller failover and inflates rebalance time across the whole cluster.
Fixing Silent Data Loss in a Fintech Payments Event Pipeline
A mid-size fintech's order-and-payments platform published payment lifecycle events to Kafka using default producer settings. During a routine rolling restart of the Kafka cluster, a handful of acknowledged payment events never appeared downstream, and the discrepancy only surfaced weeks later during a compliance reconciliation audit.
- 1The platform team audited producer configs and found acks=1 with no idempotence enabled, meaning acknowledgements only waited on the leader's local write.
- 2Root cause: during the rolling restart, a leader failover happened after the producer received its ack but before followers had replicated the record, silently dropping it.
- 3The team moved every payments topic to replication.factor=3, min.insync.replicas=2, and acks=all, and enabled enable.idempotence=true on all producers.
- 4The consume-transform-produce payment processor was rewritten to use a transactional producer with sendOffsetsToTransaction, and downstream consumers were switched to isolation.level=read_committed.
- 5Monitoring was added for ISR shrink events and under-replicated partitions, wired to PagerDuty so broker stress is caught before it can cause a failover-related loss.
- 6The team load-tested the new configuration by killing leader brokers mid-traffic in staging to confirm zero acknowledged records were ever lost.
Top Must-Know Interview Questions & Model Answers
Q1: Why does Kafka only guarantee ordering within a partition, and not across an entire topic?
- •Producers append records to a partition in the order they are sent (per producer, per partition), and consumers read a partition strictly in offset order.
- •Across partitions there is no global clock or coordination, so two records in different partitions have no defined relative order even if produced milliseconds apart.
- •To get ordering for related events, you must route them to the same partition using a consistent partition key (e.g. orderId).
Q2: What is the In-Sync Replica (ISR) set and why does it matter for durability?
- •A replica falls out of the ISR if it stops fetching or falls too far behind, which can happen under disk, network, or GC pressure.
- •acks=all actually means 'wait for acknowledgement from all current ISR members up to min.insync.replicas,' not literally every replica of the partition.
- •If the ISR shrinks to fewer members than min.insync.replicas, producers using acks=all will start receiving NotEnoughReplicasException.
Q3: Walk through exactly what happens when a partition's leader broker crashes.
- •The controller (elected via the KRaft Raft quorum, or historically via ZooKeeper) monitors broker liveness through heartbeats/session expiry.
- •On detecting the failure, it selects a replacement leader from the ISR (never an out-of-sync replica, unless unclean leader election is explicitly enabled).
- •The new leader starts accepting produce/fetch requests; producers and consumers get a NotLeaderForPartitionException on their next request and refresh metadata to find the new leader.
Q4: What replaced ZooKeeper in modern Kafka, and why was the change made?
- •ZooKeeper added an entirely separate distributed system to operate, upgrade, and secure, plus a metadata sync path that limited controller failover speed and partition-count scalability.
- •KRaft controllers store the metadata log as a Kafka-style replicated log, enabling faster controller failover and support for clusters with far more partitions.
- •Operationally this means one less system to run, patch, and monitor, and a simpler mental model: everything is 'just Kafka.'
Q5: What is unclean leader election, and why is it risky?
- •If every ISR replica is down, a cluster with unclean.leader.election.enable=false will keep the partition unavailable for writes/reads rather than risk data loss.
- •Enabling it lets an out-of-sync replica take over, silently truncating any records the new leader never received.
- •It should generally be disabled for financial, audit, or otherwise loss-sensitive topics, and can be left enabled only where availability strictly outweighs data completeness.
Q6: What do acks=0, acks=1, and acks=all actually guarantee for a producer?
- •acks=0: the producer doesn't wait for any broker response -- maximum throughput, but records can be silently lost on any network or broker issue.
- •acks=1: the leader acknowledges after its own local append, before followers replicate -- a leader crash immediately afterward loses the record.
- •acks=all (-1): the leader waits until min.insync.replicas members of the ISR have replicated the record, the strongest built-in durability guarantee.
Q7: How does the idempotent producer prevent duplicate writes on retries?
- •When a producer retries a send after a timeout (even though the original write may have actually succeeded), it resends the same PID + sequence number.
- •The broker tracks the last committed sequence number per PID per partition and silently discards a duplicate instead of appending it again.
- •This only de-duplicates producer-side retries; it does not by itself give you exactly-once across a full read-process-write pipeline -- that requires transactions on top.
Q8: How does Kafka's default partitioner decide which partition a keyed record goes to?
- •The same key always maps to the same partition as long as the partition count is unchanged, which is what gives you per-key ordering guarantees.
- •For records with a null key, Kafka's sticky partitioner batches several consecutive records onto the same partition before switching, to improve batch efficiency rather than round-robining every single record.
- •Increasing partition count later changes the hash-to-partition mapping for keyed records, so existing keys can start landing on different partitions going forward.
Q9: How do batch.size and linger.ms affect producer throughput versus latency?
- •With linger.ms=0 (default), the producer sends as soon as a batch is ready, which can mean many small, inefficient network requests under moderate load.
- •Setting linger.ms to even 5-20ms lets more records accumulate into fewer, larger, more compressible batches, improving throughput substantially.
- •batch.size caps memory used per batch; once reached, the batch is sent immediately even if linger.ms hasn't elapsed.
Q10: What happens if you set replication.factor=3 but min.insync.replicas=1?
- •min.insync.replicas defines the minimum ISR size required to accept an acks=all write; setting it to 1 means the leader alone can satisfy the requirement.
- •If the leader crashes immediately after acking a write that followers haven't replicated yet, that record is lost even though replication.factor was 3.
- •For real durability guarantees, min.insync.replicas should be at least 2 with replication.factor=3, tolerating one broker failure without blocking writes.
Q11: How does a Kafka consumer group achieve parallel consumption of a topic?
- •A group coordinator broker tracks group membership and drives partition assignment using the configured assignor strategy.
- •If a topic has 12 partitions and the group has 4 consumers, each consumer gets 3 partitions on average; adding a 5th consumer redistributes partitions, but adding a 13th consumer leaves it permanently idle.
- •Two separate consumer groups reading the same topic are fully independent -- each group gets its own copy of every record.
Q12: What triggers a consumer group rebalance, and what does it cost?
- •Common triggers: a rolling deployment restarting consumer pods, a consumer exceeding max.poll.interval.ms because processing took too long, or a network partition causing missed heartbeats.
- •Under the legacy eager protocol, ALL consumers stop processing ALL partitions during the rebalance, even ones that aren't moving.
- •Frequent rebalances ('rebalance storms') can make a consumer group spend more time reorganizing than actually processing records.
Q13: What's the difference between eager rebalancing and cooperative-sticky rebalancing (KIP-429)?
- •In the eager protocol, even consumers whose partition assignment won't change still stop processing during the rebalance window.
- •Cooperative-sticky rebalancing runs in two phases: it first computes the new assignment, then only revokes partitions from consumers that are losing them, letting everyone else keep consuming uninterrupted.
- •This is configured via partition.assignment.strategy=org.apache.kafka.clients.consumer.CooperativeStickyAssignor and is the recommended default for any non-trivial consumer group.
Q14: What is static group membership and when should you use it?
- •Without static membership, every consumer restart (e.g. during a rolling deploy or transient crash) is seen as a member leaving and later rejoining, each of which triggers its own rebalance.
- •With group.instance.id set, the coordinator recognizes the returning consumer and simply restores its previous partition assignment within session.timeout.ms.
- •This is especially valuable for large consumer groups or stateful Kafka Streams applications where rebalances are expensive to recover from.
Q15: What's the difference between session.timeout.ms and max.poll.interval.ms?
- •Heartbeats are sent on a separate thread from record processing, so a slow-processing consumer can still appear 'alive' via session.timeout.ms while actually stuck.
- •max.poll.interval.ms exists specifically to catch that case: if poll() isn't called again within this window, the consumer is force-removed from the group and its partitions are reassigned.
- •Long, variable-latency processing (e.g. calling a slow downstream API per record) should raise max.poll.interval.ms or move work off the poll loop, not just extend session.timeout.ms.
Q16: How are consumer offsets stored and committed in Kafka?
- •enable.auto.commit=true (the default) commits offsets on a fixed interval regardless of whether processing actually finished, which can silently produce at-most-once behavior on crashes.
- •Manual commits (commitSync/commitAsync) after successful processing give at-least-once semantics: on crash and restart, some records may be reprocessed but none are skipped.
- •__consumer_offsets is itself a compacted topic, so only the latest committed offset per group/topic/partition key is retained.
Q17: Explain the difference between at-most-once, at-least-once, and exactly-once delivery in Kafka.
- •At-most-once: commit the offset before (or without confirming) processing completes -- a crash after commit but before processing loses the record.
- •At-least-once: commit the offset only after processing succeeds -- a crash after processing but before commit reprocesses the record on restart, producing duplicates unless the downstream write is idempotent.
- •Exactly-once: achieved end-to-end via the idempotent producer, Kafka transactions wrapping the consume-transform-produce loop, and read_committed on downstream consumers so they never see uncommitted/aborted writes.
Q18: How do Kafka transactions implement exactly-once processing across a consume-transform-produce loop?
- •The producer calls beginTransaction(), sends output records, calls sendOffsetsToTransaction() to bundle the input offset commit into the same transaction, and finally commitTransaction().
- •The transaction coordinator writes markers to a special __transaction_state topic and to each involved partition indicating the transaction's commit/abort outcome.
- •Downstream consumers reading with isolation.level=read_committed will never see the produced records (or the offset commit) unless the transaction actually committed, making the whole loop atomic.
Q19: What is the read_committed isolation level, and why does the consumer need it?
- •The default isolation.level is read_uncommitted, which returns every record written to the log regardless of transactional outcome, including ones that will later be marked aborted.
- •read_committed makes the consumer buffer and withhold records until it sees the transaction's commit marker, effectively hiding aborted-transaction records entirely.
- •This is required on the consuming side of any exactly-once pipeline -- an idempotent, transactional producer provides no end-to-end guarantee if the consumer is still reading read_uncommitted.
Q20: What is producer fencing, and when does it occur?
- •Each transactional.id is associated with a monotonically increasing epoch; calling initTransactions() bumps the epoch for that transactional.id.
- •If an older producer instance (e.g. from a crashed pod that's still partially running) tries to write or commit using a stale epoch, the broker rejects it with a ProducerFencedException.
- •This typically happens after a rolling restart or failover where two instances briefly hold the same logical transactional.id before the old one is fully torn down.
Q21: What is the difference between a KStream and a KTable in Kafka Streams?
- •Every record on a KStream is treated as a new, independent event (e.g. 'a click happened'), so nothing is ever overwritten.
- •A KTable interprets each new record for a key as an update to that key's current value (e.g. 'a user's latest profile'), conceptually behaving like a compacted, continuously changing table.
- •KStream-KTable joins let you enrich a stream of events with the latest reference/lookup data, a very common real-world pattern (e.g. enriching orders with the customer's current tier).
Q22: How does Kafka Streams achieve fault tolerance for stateful operations like aggregations?
- •Each state store (e.g. from a groupBy().count()) is backed by a dedicated changelog topic that Kafka Streams manages automatically.
- •If the instance owning a stateful task dies, Kafka Streams reassigns that task to another instance, which restores the state store by replaying the changelog topic from the beginning (or from a local standby replica if configured).
- •Standby replicas (num.standby.replicas > 0) pre-warm a hot copy of the state store on another instance, dramatically reducing failover recovery time.
Q23: What is ksqlDB, and when would you choose it over hand-written Kafka Streams code?
- •It's a strong fit for operational dashboards, quick data exploration, and teams without deep Java expertise who still need continuous stream transformations.
- •It trades some flexibility for velocity: complex custom processors, fine-grained punctuation/timer logic, or non-trivial business logic are usually easier to express directly in the Kafka Streams DSL or Processor API.
- •Both ultimately compile down to the same underlying Kafka Streams topology and inherit the same fault-tolerance and exactly-once guarantees.
Q24: What does processing.guarantee=exactly_once_v2 actually do in Kafka Streams?
- •Under exactly_once_v2, a single transactional producer is shared efficiently across all of an application instance's tasks (an improvement over the original exactly_once mode's per-task producer overhead).
- •On a task failure mid-transaction, the transaction is aborted; on restart, the task's changelog-backed state is restored and processing resumes from the last successfully committed offset with no partial writes visible downstream.
- •This guarantee only holds within the Kafka ecosystem itself; a side-effect to an external system (e.g. calling a REST API mid-topology) is not covered and needs its own idempotency strategy.
Q25: What's the difference between time/size-based retention and log compaction?
- •retention.ms/retention.bytes are appropriate for plain event logs where you want a bounded historical window (e.g. keep 7 days of clickstream events).
- •cleanup.policy=compact is designed for changelog-style or 'latest state' topics (e.g. a KTable changelog, or a CDC feed of the current row state), where only the newest value per key matters.
- •Deleting a key under compaction requires writing a tombstone (a record with that key and a null value), which is itself removed only after delete.retention.ms passes.
Q26: How do you calculate and monitor consumer lag in production?
- •kafka-consumer-groups.sh --describe --group <group> gives a point-in-time snapshot of current offset, log-end-offset, and lag per partition.
- •Tools like Burrow or a Prometheus JMX exporter scraping broker/consumer metrics let you graph lag over time and alert on its rate of growth, not just its absolute value.
- •A consumer group with rising lag on only a subset of partitions usually points to data skew (a hot key) rather than an overall capacity problem.
Q27: How do you decide how many partitions a new Kafka topic should have?
- •Partition count sets the ceiling on consumer parallelism within a group, so under-provisioning limits future horizontal scaling of consumers.
- •Over-provisioning has real costs too: more partitions mean more open file handles per broker, higher replication traffic, slower controller failover, and longer rebalances.
- •Because increasing partition count changes the key-to-partition hash mapping, plan for a reasonable ceiling upfront rather than repeatedly resizing a topic with ordering-sensitive keys.
Q28: What is an under-replicated partition, and why is it treated as an early warning sign?
- •A rising under-replicated-partitions count often precedes a full broker failure, a disk saturating with I/O, or a network partition slowing follower fetch requests.
- •While under-replicated, the effective durability of acks=all writes is reduced, since fewer replicas are actually confirming the write even though min.insync.replicas may still nominally be met.
- •Combined with ISR-shrink/expand event logs, this metric lets operators intervene (rebalance load, add capacity, investigate a slow disk) before the cluster loses an entire replica set for a partition.
Q29: How does compression (e.g. lz4, zstd) affect Kafka's throughput and CPU trade-offs?
- •Compression is applied per batch on the producer, and the broker stores and replicates the already-compressed batch as-is, saving both network bandwidth to followers and disk space.
- •lz4 favors speed with a modest compression ratio; zstd generally achieves a better compression ratio at somewhat higher CPU cost, and gzip is the slowest of the common options.
- •Because compression operates per batch, a larger batch.size/linger.ms setting improves compression efficiency further, since there's more repetitive data per batch to compress.
Mistakes That Sink Otherwise Strong Candidates
Why it happens: These are close to Kafka's historical defaults, throughput looks great in load tests, and the durability gap only shows up during an actual leader failover in production.
The fix: Set acks=all with replication.factor=3 and min.insync.replicas=2, so the cluster tolerates one broker failure without losing acknowledged writes.
Why it happens: Message queues from prior experience often imply a single global order, and Kafka's partitioned model isn't obvious from the client API alone.
The fix: Only rely on ordering within a partition, and route causally related records to the same partition using a consistent key.
Why it happens: More partitions feel like free future flexibility, and the operational cost isn't visible until the cluster has hundreds of over-sized topics.
The fix: Size partitions for realistic near-term throughput with modest headroom; grow partition count later rather than starting oversized.
Why it happens: It's the historical default and rarely gets revisited once a consumer group is working.
The fix: Switch to the cooperative-sticky assignor so rebalances only move the specific partitions that need to change instead of pausing the whole group.
Why it happens: Auto-commit is the default and requires no extra code, so it's easy to leave in place without thinking through the failure window.
The fix: Disable auto-commit and commit offsets manually only after processing has verifiably completed, accepting occasional reprocessing over silent loss.
Why it happens: The config is often copy-pasted from a template without realizing it must uniquely identify one logical producer instance.
The fix: Scope transactional.id uniquely per instance/partition (e.g. include a stable instance or shard identifier) to avoid ProducerFencedException storms.
Why it happens: Lag isn't visible without dedicated tooling, and a healthy-looking consumer process gives no indication it's falling behind.
The fix: Export lag metrics via JMX/Burrow into Prometheus and Grafana, and alert on lag growth rate per partition, not just an absolute threshold.
Why it happens: Compaction and retention both 'clean up old data,' so the two are easily confused when configuring a new topic.
The fix: Use compaction only for changelog/latest-state topics; use time or size-based retention for topics where full historical event replay matters.
Why it happens: It seems intuitive that adding consumers always adds throughput.
The fix: Increase partition count alongside consumer count -- any consumer instance beyond the partition count will sit permanently idle.
Quick-Reference Cheat Sheet
Recommended Practice Quizzes on QuizCluster
Test your retention and prepare for timed live coding and MCQ technical screening rounds:
Docker & Kubernetes
Test how you'd containerize and deploy Kafka brokers, consumers, and Kafka Streams apps on Kubernetes with proper resource and storage configuration.
High-Level System Design (HLD)
Practice designing event-driven architectures where Kafka sits at the center of ingestion, fan-out, and asynchronous processing pipelines.
Frequently Asked Questions
Is Kafka a message queue or a streaming platform?
Both, in practice. Kafka behaves like a durable, replayable log rather than a traditional queue (messages aren't removed on consumption), which is what lets it support classic pub/sub messaging, event sourcing, and continuous stream processing (via Kafka Streams/ksqlDB) on the same underlying storage.
How many partitions should a Kafka topic have?
Size for your realistic near-term throughput divided by a single partition's sustainable throughput, plus modest headroom for consumer scaling. Avoid drastically over-provisioning 'for the future' since more partitions increase rebalance time, open file handles, and replication overhead cluster-wide.
What happens to in-flight messages if a Kafka broker goes down?
If the broker was a follower, nothing user-visible happens beyond a temporarily smaller ISR. If it was a leader, the controller promotes an ISR replica to leader; producers using acks=all and min.insync.replicas>=2 will not lose already-acknowledged records, while acks=1 writes acknowledged just before the crash can be lost.
Do I still need ZooKeeper for Kafka in 2026?
No, for new deployments. Modern Kafka runs in KRaft mode, where a quorum of controller nodes manages cluster metadata and leader election using Raft consensus directly inside Kafka, eliminating the separate ZooKeeper dependency entirely.