REST API Design Interview Guide: Authentication, Pagination, Versioning & Rate Limiting
From Resource Modeling to OAuth2, Cursor Pagination & Token Bucket Rate Limiters at Scale
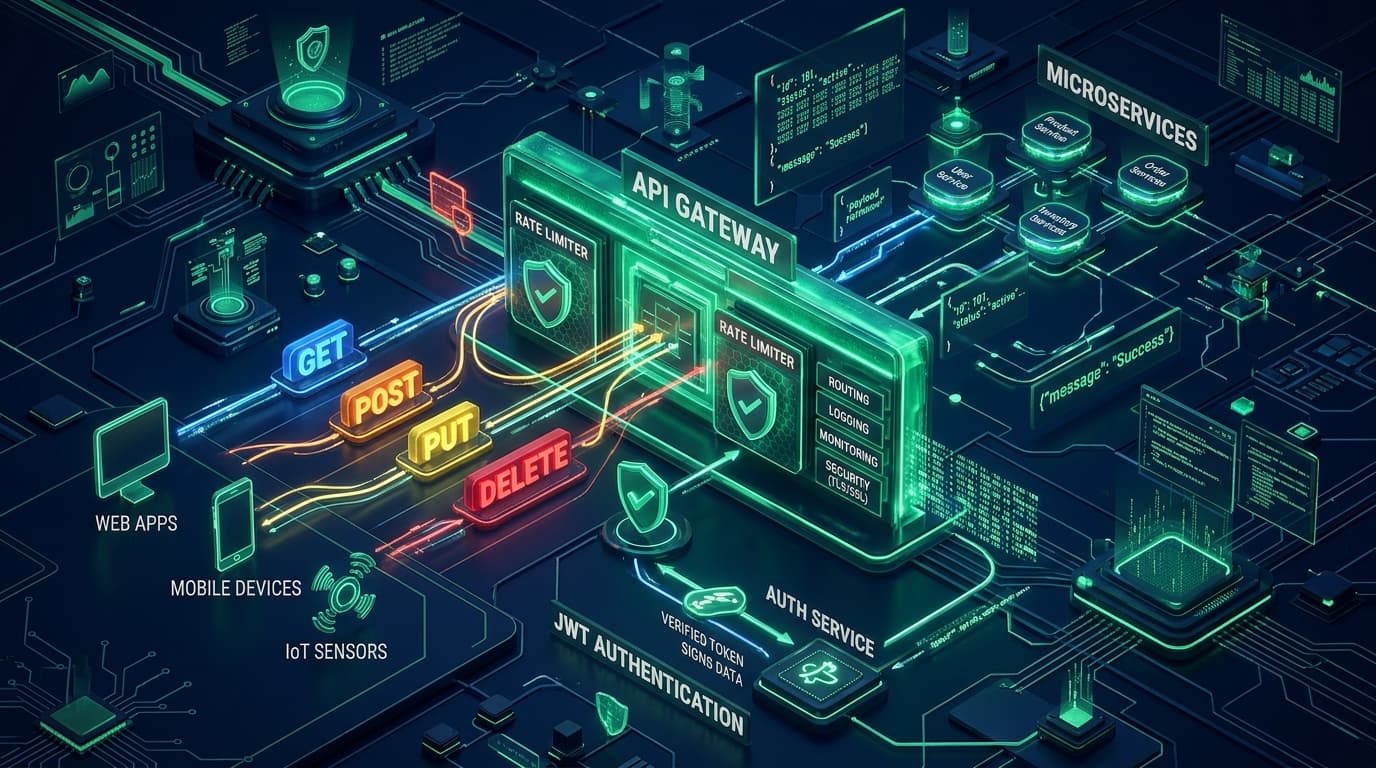
What You Must Master to Clear This Track
- REST is a set of architectural constraints (statelessness, uniform interface, cacheability), not just 'JSON over HTTP' — interviewers probe whether you actually understand the trade-offs behind each one.
- Know all three authentication models cold: API keys for service-to-service trust, JWTs for stateless session claims, and OAuth2 Authorization Code + PKCE for delegated third-party access.
- Cursor (keyset) pagination beats offset pagination at scale because it avoids re-scanning skipped rows and stays stable when rows are inserted or deleted mid-page.
- Version APIs defensively from day one (URI or header versioning) and treat every field addition, removal, or type change as a backward-compatibility decision, not an afterthought.
- Idempotency keys and a standardized error envelope are what separate a toy CRUD API from a production-grade contract that survives retries, timeouts, and partial failures.
Step-by-Step Study Plan
Follow this sequential roadmap designed to take you from core foundations to advanced architecture and mock interviews.
Architectural Constraints, Resource Design & HTTP Semantics
Master Roy Fielding's constraints (statelessness, uniform interface, layered system), correct HTTP verb/status code usage, and clean noun-based resource URLs.
- •Design resource hierarchies for a nested domain (e.g. /orders/{id}/line-items) with correct plural nouns and no verbs in URLs.
- •Map every CRUD operation to the correct HTTP method and idempotency semantics (GET, PUT, PATCH, DELETE, POST).
- •Practice explaining statelessness and its trade-off against convenience features like server-side sessions.
- •Redesign a legacy RPC-style API ('/getUserById?id=5') into RESTful resource form as a drill.
- •Write out the full HTTP status code table (2xx/3xx/4xx/5xx) from memory with one real use case per code.
Security Boundaries, Data Slicing & Long-Term Contract Evolution
Deep-dive OAuth2 Authorization Code flow with PKCE, JWT structure and revocation trade-offs, offset vs keyset pagination, and the three major versioning strategies.
- •Trace the full OAuth2 Authorization Code + PKCE handshake end-to-end, including token refresh.
- •Implement a cursor-based pagination query using a composite (timestamp, id) key with a supporting index.
- •Compare URI versioning, header/Accept versioning, and content negotiation with real backward-compatibility scenarios.
- •Decode a real JWT on jwt.io and identify which claims are safe to trust without server-side verification.
- •Write a migration plan for renaming a field in a v1 API response without breaking existing mobile clients.
Production Hardening for Abuse, Retries & Partial Failure
Token bucket vs sliding window rate limiting, idempotency keys for safe retries, standardized error envelopes, and mock interview drills tying it all together.
- •Implement a distributed token bucket limiter backed by Redis and reason about race conditions across app instances.
- •Design an idempotency-key mechanism for a payment/charge endpoint that is safe under network retries.
- •Draft a single standardized error response shape covering validation, auth, and server errors consistently.
- •Run 3 mock interviews designing a public API (e.g. a bookings API) end-to-end in 45 minutes.
- •Review real-world API docs (Stripe, GitHub, Twilio) and reverse-engineer their pagination, versioning, and error conventions.
1. REST Architectural Constraints & Resource Modeling
REST is not 'HTTP plus JSON' — it is a specific set of architectural constraints defined by Roy Fielding's dissertation. Interviewers use resource modeling questions to separate candidates who copy convention from those who understand why the convention exists.
Every request must contain all information needed to process it; the server holds no client session state between requests, which is what enables horizontal scaling behind any load balancer.
Resources are identified by nouns (/orders/{id}, not /getOrder), manipulated through standard HTTP verbs, and represented in a consistent, self-descriptive media type such as application/json.
Responses explicitly declare whether they are cacheable (Cache-Control, ETag) so clients and intermediary proxies can reduce redundant round-trips without violating correctness.
Clients cannot tell (and shouldn't need to know) whether they are talking directly to the origin server or through a gateway/CDN/cache layer in between.
The most-ignored constraint: responses should include links to valid next actions (e.g. a 'cancel' link on a pending order), letting clients navigate the API dynamically instead of hardcoding URLs.
- When asked to 'design a REST API' in an interview, start by listing resources (nouns) and their relationships before touching a single endpoint path.
- Justify verb choices explicitly: PUT is a full idempotent replace, PATCH is a partial (often non-idempotent) update, POST is for creation or non-idempotent actions.
- Using verbs in URLs (/createOrder, /getUserDetails) instead of resource nouns with HTTP methods carrying the verb semantics.
- Returning 200 OK for every response regardless of outcome, which forces clients to parse the body just to know if something failed.
3. Pagination Strategies: Offset vs Cursor/Keyset
Pagination looks trivial until the dataset is billions of rows and users are scrolling an infinite feed — this is one of the highest-signal 'have you actually run this in production' questions in backend interviews.
Simple to implement (OFFSET n LIMIT m) and allows random page jumps, but the database must scan and discard all skipped rows, making deep pages progressively slower.
Uses the last seen row's sort key (typically a composite of timestamp + unique id) as an opaque cursor in a WHERE clause, so the database seeks directly to the next page via an index instead of scanning.
Offset pagination can skip or duplicate rows if items are inserted/deleted between page requests; keyset pagination stays consistent because each page is anchored to a specific row, not a row count.
Keyset pagination typically cannot cheaply return 'total pages' or support random page jumps — most infinite-scroll UIs (feeds, chat, notifications) don't need that anyway.
-- Keyset pagination on a composite, unique, indexed key.
  -- The opaque cursor the client holds encodes the last row's (created_at, id).
  SELECT id, title, created_at
  FROM articles
  WHERE (created_at, id) < ($1::timestamptz, $2::uuid)  -- cursor from previous page
  ORDER BY created_at DESC, id DESC
  LIMIT 20;

  -- This index turns the WHERE + ORDER BY above into a fast index range scan
  -- instead of a full table scan followed by an in-memory sort.
  CREATE INDEX idx_articles_created_at_id
ON articles (created_at DESC, id DESC);- When asked 'how would you paginate a social feed', immediately reach for cursor pagination and justify it with the insert-during-scroll consistency argument.
- Base64-encode the cursor (e.g. {created_at, id}) so it's opaque to clients — this lets you change the underlying sort key later without breaking the API contract.
- Using OFFSET on a table with millions of rows for deep pages, causing full scans that get slower with every page the user requests.
- Exposing raw internal IDs or unencoded sort keys as the cursor, which leaks implementation details and breaks if the schema changes.
4. Versioning, Rate Limiting, Idempotency & Error Contracts
The last mile of API design is what keeps a contract alive for years: how you evolve it without breaking clients, how you protect it from abuse, and how you make it safe to retry when the network fails halfway through a request.
URI versioning (/v1/orders) is explicit and cache-friendly but clutters URLs; header versioning (Accept: application/vnd.api.v2+json) keeps URLs stable but is less discoverable and harder to test in a browser.
Adding optional fields is safe; renaming, removing, or changing the type of an existing field is a breaking change that requires a new version or a carefully staged dual-write/dual-read migration.
Token bucket allows controlled bursts while enforcing an average rate; sliding window log/counter gives smoother, more precise limits than fixed windows, which suffer from boundary burst spikes.
A client-generated key (e.g. Idempotency-Key header) lets a server safely deduplicate retried POST requests — critical for payments, order creation, and any non-idempotent side effect over an unreliable network.
A consistent { error: { code, message, details, requestId } } shape across every endpoint lets client SDKs handle errors generically instead of branching per-endpoint.
// Atomic token bucket implemented as a Redis Lua script so concurrent
  // requests across many stateless app instances never race on read-modify-write.
  import { Redis } from "ioredis";

  const redis = new Redis(process.env.REDIS_URL);

  const TOKEN_BUCKET_SCRIPT = `
  local key = KEYS[1]
  local capacity = tonumber(ARGV[1])
  local refillRatePerSec = tonumber(ARGV[2])
  local now = tonumber(ARGV[3])
  local requested = tonumber(ARGV[4])

  local bucket = redis.call("HMGET", key, "tokens", "timestamp")
  local tokens = tonumber(bucket[1])
  local lastRefill = tonumber(bucket[2])

  if tokens == nil then
    tokens = capacity
    lastRefill = now
  end

  local elapsed = math.max(0, now - lastRefill)
  tokens = math.min(capacity, tokens + elapsed * refillRatePerSec)

  local allowed = tokens >= requested
  if allowed then
    tokens = tokens - requested
  end

  redis.call("HMSET", key, "tokens", tokens, "timestamp", now)
  redis.call("EXPIRE", key, 3600)

  return allowed and 1 or 0
  `;

  export async function isRequestAllowed(
    clientId: string,
    capacity = 100,
    refillRatePerSecond = 10,
  ): Promise<boolean> {
    const now = Date.now() / 1000;
    const result = await redis.eval(
      TOKEN_BUCKET_SCRIPT,
      1,
      `rate_limit:${clientId}`,
      capacity,
      refillRatePerSecond,
      now,
      1,
    );
    return result === 1;
}- When comparing rate limiting algorithms, lead with the trade-off: fixed window is cheapest but allows 2x burst at window boundaries; sliding window log is most accurate but costs more memory per key; token bucket is the pragmatic middle ground most APIs (Stripe, GitHub) actually ship.
- Always return 429 Too Many Requests with a Retry-After header (and ideally X-RateLimit-Remaining/X-RateLimit-Reset) so well-behaved clients can back off automatically.
- Storing rate limit counters in local process memory in a horizontally scaled fleet, which lets each instance independently allow up to the limit — multiplying the effective limit by the instance count.
- Making a payment or order-creation endpoint retry-unsafe by relying only on client-side 'don't double click' UX instead of a server-side idempotency key.
- Breaking existing clients by silently changing a field's type or removing it in the current API version instead of introducing a new version or an additive migration.
Migrating a Booking Platform's API from Offset Pagination to Cursor Pagination Under Load
A mid-size travel booking platform's public search API used simple OFFSET/LIMIT pagination on a `listings` table that had grown from 200K to 40M rows over two years. During peak season, partner integrations paginating deep into search results (page 200+) were timing out and causing database CPU spikes that degraded the primary booking flow.
- 1The team instrumented slow query logs and confirmed OFFSET-heavy queries on deep pages were responsible for over 30% of database CPU during peak traffic windows.
- 2They introduced a new cursor-based pagination parameter (`after` cursor encoding a base64 {sort_score, id} tuple) alongside the existing offset parameter, keeping the old behavior available under a deprecation notice rather than breaking partners immediately.
- 3A composite index on (sort_score DESC, id DESC) was added to support the new keyset queries as fast index range scans instead of full sorts.
- 4Partner-facing documentation and SDKs were updated with a 90-day migration window, and a `Deprecation` response header was added to every offset-paginated response to nudge automated clients.
- 5The team monitored per-partner API version usage via a dashboard, reaching out directly to the last handful of integrations still on offset pagination before the sunset date.
- 6Old OFFSET-based endpoints were removed only after usage dropped below 1% of total traffic for two consecutive weeks.
Top Must-Know Interview Questions & Model Answers
Q1: What makes an API 'RESTful'? Explain Roy Fielding's core architectural constraints.
- •Statelessness means each request carries all context needed to process it; the server stores no per-client session between calls.
- •Uniform interface means resources are addressed by URIs and manipulated through a small, standard set of HTTP verbs with self-descriptive representations.
- •Cacheability and layered system let intermediaries (CDNs, gateways) sit transparently between client and origin server without breaking correctness.
Q2: Why does statelessness matter for a REST API, and what does it cost you?
- •Because no session lives on a specific server, a load balancer can round-robin requests freely and instances can be added/removed without session affinity.
- •The trade-off is repeated overhead — every request re-sends auth tokens and any state the server would otherwise have remembered.
- •Session-like features (shopping carts, wizards) must be pushed to the client or a shared store (Redis, DB) rather than in-process memory.
Q3: How should you model and name resources in REST URLs?
- •/orders and /orders/{id} represent the collection and a single resource; /orders/{id}/line-items represents a nested sub-collection.
- •Actions that don't map cleanly to CRUD (e.g. 'cancel an order') are modeled as a sub-resource or state transition: POST /orders/{id}/cancel, not /cancelOrder.
- •Query parameters handle filtering, sorting, and pagination (?status=shipped&sort=-created_at) rather than being baked into the path.
Q4: What is HATEOAS, and why do most production APIs skip it?
- •A HATEOAS response for a pending order might include links like { rel: 'cancel', href: '/orders/42/cancel' } only when cancellation is currently valid.
- •It decouples clients from hardcoded URL structures, in theory allowing the server to change routes without breaking clients that follow links.
- •In practice, most teams pair versioned, well-documented REST endpoints with generated SDKs instead, since true hypermedia-driven clients are rare outside specific ecosystems (e.g. Stripe's expandable objects, PayPal's HAL-based APIs).
Q5: Walk through the OAuth 2.0 Authorization Code flow with PKCE end-to-end.
- •PKCE (Proof Key for Code Exchange) prevents a malicious app from stealing the authorization code mid-redirect and exchanging it itself, since only the original client holds the code_verifier.
- •The state parameter round-trips through the redirect to prevent CSRF against the callback endpoint.
- •The final token exchange happens server-to-server (or with PKCE, even from a public client) and returns an access_token for API calls plus a refresh_token for renewing access without re-prompting the user.
Q6: What's the difference between authentication and authorization?
- •A JWT's signature verification is authentication (proving the token was issued by a trusted party for a specific subject); the scopes/roles inside it drive authorization decisions.
- •You can authenticate successfully and still be denied — e.g. a valid logged-in user hitting an admin-only endpoint returns 403 Forbidden, not 401 Unauthorized.
- •401 means 'who are you, please authenticate'; 403 means 'I know who you are, and you're not allowed to do this.'
Q7: How do JWTs work, and what are the risks of storing them client-side?
- •The payload (claims like sub, exp, scope, iat) is readable by anyone who has the token — never put secrets in it.
- •Signature verification proves the token wasn't tampered with and came from a trusted issuer, but says nothing about whether it's been revoked since issuance.
- •For browser clients, httpOnly + Secure + SameSite cookies are safer than localStorage because JavaScript (and therefore an XSS payload) cannot read httpOnly cookies.
Q8: When would you use a simple API key instead of OAuth2, and what are its limitations?
- •A weather API or internal microservice calling another microservice typically just needs to prove 'which application is calling', which an API key does cheaply.
- •Unlike OAuth2 tokens, API keys usually don't carry scopes or expiry by default, so a leaked key often grants full access until someone notices and rotates it.
- •Best practice: hash API keys at rest (like passwords), support multiple active keys per client for zero-downtime rotation, and log key usage for anomaly detection.
Q9: How do you handle JWT revocation given that tokens are stateless by design?
- •A denylist (e.g. in Redis, keyed by jti with TTL = remaining token lifetime) lets you invalidate specific tokens early, at the cost of a lookup on every request — partially defeating JWT's statelessness benefit.
- •A cheaper pattern: store a 'token version' per user; bump it on logout/password-change, and embed the version in the JWT — any mismatch on verification means the token is stale.
- •Refresh tokens are stored server-side anyway (so they CAN be revoked instantly), and keeping access tokens short-lived bounds the blast radius of a compromised access token.
Q10: Compare offset-based pagination and cursor/keyset pagination.
- •OFFSET 100000 LIMIT 20 still requires the database to walk through 100,020 rows before returning the last 20 — an O(offset) operation.
- •Keyset pagination (WHERE (created_at, id) < (cursor_ts, cursor_id) ORDER BY ... LIMIT n) uses the index to seek directly to the right starting point, independent of how deep the page is.
- •Offset pagination can skip or duplicate rows if items are inserted/deleted between requests; keyset pagination is immune because each page is defined relative to a specific row, not a row count.
Q11: Why does offset pagination degrade in performance on large tables?
- •Even with an index on created_at, the engine must traverse the index (or table) from the start of the ordering to reach row #100,020 before it can apply LIMIT 20.
- •Deep pagination (e.g. page 5,000 of search results) can turn a sub-millisecond query into a multi-second one purely from the discarded-row scan cost.
- •This is invisible in dev/staging with small seed data and only shows up under production data volume — a classic interview 'gotcha' to flag proactively.
Q12: How do you design a stable pagination cursor when the sort key isn't unique?
- •Sorting purely by created_at can produce duplicate or skipped rows across pages if multiple rows share the same timestamp (common with bulk inserts or coarse timestamp precision).
- •WHERE (created_at, id) < (cursor_created_at, cursor_id) ORDER BY created_at DESC, id DESC establishes a strict total order even with duplicate timestamps.
- •The composite (column, id) index must match the ORDER BY direction exactly for the database to use it as an efficient range scan instead of a sort.
Q13: How would you support 'jump to page N' in a UI while primarily using cursor pagination internally?
- •Most infinite-scroll or 'load more' UIs never need random jumps, so keep the default API cursor-based for performance.
- •For admin dashboards that do need 'go to page 47', a secondary offset-style endpoint (or a periodically materialized snapshot of page boundaries) can serve that rarer use case without slowing down the primary feed.
- •Total counts on huge tables are also expensive to compute exactly — many APIs return an approximate count (e.g. from table statistics) rather than a live COUNT(*).
Q14: Compare URI versioning, header versioning, and content-negotiation versioning.
- •URI versioning is by far the most common in practice (Stripe, Twilio, GitHub) because it's trivially cacheable by URL and requires no special client tooling.
- •Header versioning avoids URL churn, which matters if URLs are used as durable identifiers (e.g. stored/bookmarked), but makes manual testing and caching by URL harder.
- •Content negotiation via media type is the most RESTful in spirit but adds friction for API consumers who now must set nonstandard Accept headers correctly.
Q15: How do you evolve an API without breaking existing clients?
- •Additive changes: adding a new optional response field, adding a new optional request parameter with a sensible default, adding new endpoints.
- •Breaking changes: removing a field, renaming a field, changing a field's type (string to number), making an optional field required, or changing error response shapes.
- •For unavoidable breaking changes, use expand-and-contract: add the new field alongside the old one, migrate clients over a deprecation window, then remove the old field in the next major version.
Q16: What's the practical difference between a breaking and non-breaking API change?
- •Renaming a field from user_id to userId looks trivial but breaks every client parsing the old key.
- •Changing a numeric ID field from an integer to a string (common when migrating to UUIDs) breaks strongly-typed clients even if the JSON still 'looks like' a valid value.
- •Tightening validation (e.g. making an email field require a valid format when it previously accepted any string) can break existing integrations sending data that used to pass.
Q17: How do you deprecate an API version safely in production?
- •Return a Deprecation: true header (and ideally a Sunset: <date> header) on every response from the deprecated version so automated client tooling can detect it.
- •Instrument per-version request metrics so you know exactly which clients/API keys are still on the old version before cutting it off.
- •Provide a migration guide and, where possible, a compatibility shim so most clients can move with minimal code changes rather than a rewrite.
Q18: Compare token bucket, leaky bucket, fixed window, and sliding window rate limiting algorithms.
- •Fixed window counters reset a counter every N seconds — trivial to implement but a client can send the limit right before AND right after a window boundary, doubling the effective burst.
- •Sliding window log stores individual request timestamps for exact accuracy; sliding window counter approximates it cheaply by weighting the previous and current window counts.
- •Token bucket refills tokens continuously at a fixed rate up to a capacity ceiling, letting clients burst up to that ceiling then throttling to the refill rate — this is what most production APIs (Stripe, GitHub) actually use.
Q19: How do you implement rate limiting consistently across a fleet of stateless API servers?
- •In-memory per-instance counters fail because each of N instances independently enforces the full limit, multiplying the effective ceiling by N.
- •A naive GET-then-SET against Redis from multiple instances still races; wrapping the whole check in a Lua script (or using Redis's atomic INCR + EXPIRE pattern) makes it a single indivisible operation.
- •At extreme scale, some systems trade perfect accuracy for lower latency using local approximate counters that periodically sync to a central store (eventually-consistent rate limiting).
Q20: What HTTP status code and headers should a rate-limited API return?
- •429 is the standard, purpose-built status for this scenario — using 403 or 503 instead loses semantic meaning and breaks client libraries that specifically handle 429 with backoff.
- •Retry-After can be a number of seconds or an HTTP date, giving the client a concrete signal instead of guessing a backoff interval.
- •Exposing remaining-quota headers on every response (not just when limited) lets clients proactively slow down before ever seeing a 429.
Q21: How do you rate-limit fairly per-user vs per-IP, and why does it matter?
- •Public login or signup endpoints have no authenticated identity yet, so per-IP (or per-IP + fingerprint) limiting is the only option there, accepting its imprecision.
- •Once a request is authenticated, keying the limiter on user/API-key id is strictly fairer and harder to evade than per-IP.
- •Layered limiting is common in practice: a loose per-IP limit at the edge (basic abuse protection) plus a stricter per-user/per-key limit at the application layer (fair quota enforcement).
Q22: What does idempotency mean for HTTP methods, and which methods are idempotent by spec?
- •PUT /users/5 {name: 'Alex'} run twice leaves the same end state both times — idempotent by definition, even though the second call still does work.
- •POST /orders run twice (without extra safeguards) creates two separate orders — this is exactly the 'double-submit on a flaky network' problem idempotency keys solve.
- •PATCH is context-dependent: {status: 'shipped'} is idempotent, but {increment_stock: 1} is not, since repeating it changes the result each time.
Q23: How do you make a non-idempotent endpoint like a payment charge safe to retry?
- •The client generates the idempotency key once per user action (e.g. once per 'Pay Now' click) and resends the same key on every retry of that same action, including across network timeouts.
- •The server persists {idempotency_key -> response, status} typically in the same transaction as the side effect, so a crash between charging the card and recording the key can't cause a silent duplicate charge.
- •Keys are usually scoped per endpoint and expired after a reasonable window (e.g. 24 hours) to bound storage growth.
Q24: Design a standardized error response format for a REST API.
- •`code` should be a stable, machine-readable string (e.g. VALIDATION_ERROR, RATE_LIMITED, RESOURCE_NOT_FOUND) that won't change even if the human-readable `message` copy is edited.
- •`details` carries structured, field-level information for validation errors (e.g. an array of {field, issue} objects) so forms can highlight the exact broken input.
- •`requestId` (echoed from a request-tracing header) lets support/engineering correlate a client-reported error with server-side logs instantly.
Q25: What status code should you return for a validation failure versus a business rule failure?
- •400 signals 'the request itself is malformed' — wrong types, missing required fields, invalid JSON.
- •422 signals 'the request is well-formed and understood, but the server can't act on it' — e.g. an order request for a valid product ID that's out of stock.
- •409 Conflict is best reserved for state-conflict scenarios specifically, like a concurrent edit conflict (optimistic locking version mismatch) rather than general business-rule violations.
Q26: How do you handle partial failures in a batch API endpoint?
- •A batch of 100 'create user' operations where 97 succeed and 3 fail validation should not roll back the 97 successes just because the request-level status can't be a single clean code.
- •The response body should include a per-item array like [{ index: 0, status: 'success', id: '...' }, { index: 1, status: 'error', error: {...} }] so the client can retry only the failed subset.
- •Document clearly whether the batch is transactional (all-or-nothing) or best-effort (partial success allowed) — this is a business decision, not just an API detail, and must be explicit in the contract.
Mistakes That Sink Otherwise Strong Candidates
Why it happens: Developers coming from RPC-style or SOAP backgrounds default to function-call thinking, mapping each server operation directly to a URL.
The fix: Model resources as nouns and let the HTTP method carry the verb: GET /orders, POST /users. Reserve action-style sub-paths (POST /orders/{id}/cancel) only for state transitions that don't map cleanly to CRUD.
Why it happens: Offset pagination is the simplest thing to implement and works fine in development with small seed data, so the performance cliff only appears once the table reaches production scale.
The fix: Default to cursor/keyset pagination for any resource expected to grow past a few hundred thousand rows or be paged deeply, backed by a composite index matching the sort order.
Why it happens: localStorage is the easiest storage API to reach for and 'just works' in a quick demo, without the developer considering the XSS attack surface.
The fix: Store tokens in httpOnly, Secure, SameSite cookies so client-side JavaScript (and any injected XSS payload) cannot read them directly.
Why it happens: It's the fastest thing to prototype locally, and the bug is invisible until the service is actually scaled to multiple instances in production.
The fix: Back the rate limiter with a shared store (Redis) and update counters atomically (Lua script or atomic commands) so the limit is enforced fleet-wide, not per-instance.
Why it happens: The change looks small and internally consistent to the team making it, without accounting for external clients already depending on the old shape.
The fix: Classify every response/request shape change as additive or breaking before shipping; breaking changes go through a new version or an explicit expand-and-contract migration with a deprecation window.
Why it happens: The unhappy path (network timeout right after the server processed the request but before the client got the response) is rarely tested, so double-execution only surfaces in production incident reports.
The fix: Require an Idempotency-Key on any non-idempotent, side-effecting endpoint, and store the key-to-result mapping so retries return the original result instead of re-executing.
Why it happens: It feels 'simpler' to always return 200 and let clients check a boolean, especially when a frontend team drives the API contract informally.
The fix: Use accurate HTTP status codes as the primary signal of outcome (400/401/403/404/409/422/429/500) so infrastructure (caches, load balancers, monitoring, client libraries) can react correctly without inspecting the body.
Why it happens: Endpoints are often built by different engineers or teams over time without a shared contract enforced up front.
The fix: Define one standardized error envelope ({ error: { code, message, details, requestId } }) at the platform level and enforce it via shared middleware or a schema/lint check in CI.
Why it happens: Signature checks are the most visible part of JWT handling, so it's easy to treat 'signature valid' as equivalent to 'access still authorized'.
The fix: Keep access token lifetimes short (minutes, not days), verify a token-version or denylist claim for sensitive operations, and rely on revocable refresh tokens for the actual logout/revocation guarantee.
Quick-Reference Cheat Sheet
Recommended Practice Quizzes on QuizCluster
Test your retention and prepare for timed live coding and MCQ technical screening rounds:
JavaScript & TypeScript
Sharpen the TypeScript and async patterns behind real Node.js REST API implementations, from middleware to error handling.
High-Level System Design (HLD)
Practice designing rate limiters, API gateways, and pagination-heavy services at scale for senior system design rounds.
Frequently Asked Questions
Is GraphQL replacing REST in interviews?
No — REST remains the dominant interview topic because most companies' production APIs are still REST-based, and REST design questions (auth, pagination, versioning, rate limiting) test fundamentals that transfer to GraphQL and gRPC as well. Expect GraphQL to come up as a comparison question, not a replacement topic.
Do I need to memorize every HTTP status code for interviews?
No, but you should know the common ones cold: 200/201/204 for success variants, 400/401/403/404/409/422 for client errors, and 429/500/503 for rate limiting and server failure. Interviewers care more about WHY you'd pick 422 over 400 than whether you've memorized all 63 official codes.
Should I bring up rate limiting and idempotency even if not explicitly asked?
Yes — proactively mentioning rate limiting, idempotency, and error contracts when designing any endpoint that writes data (especially payments or order creation) is a strong signal of production experience and is exactly what separates mid-level from senior-level answers.
How deep should I go on OAuth2 if the role isn't security-focused?
Know the Authorization Code + PKCE flow well enough to draw it from memory and explain what each step prevents (CSRF via state, code interception via PKCE) — you don't need to memorize every OAuth2 grant type (implicit, client credentials, device code) in equal depth unless the role is specifically security or platform-focused.