Node.js Backend Interview Guide: Event Loop, Streams, APIs & Scaling
From libuv Internals to Production-Grade APIs, Worker Threads & Multi-Core Scaling
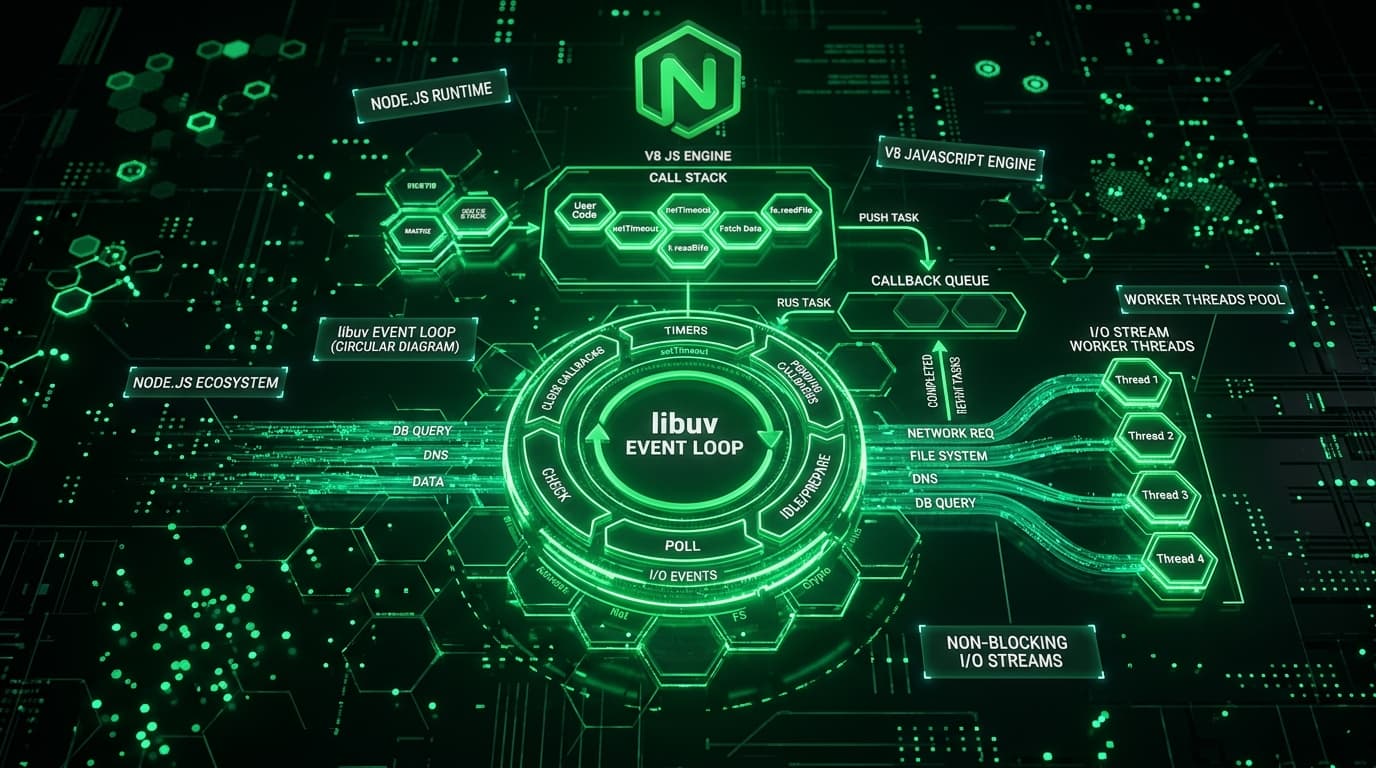
What You Must Master to Clear This Track
- Internalize the libuv event loop's six phases and how the process.nextTick and Promise microtask queues drain completely between every phase transition.
- Treat backpressure as a first-class concern: prefer stream.pipeline() and check the write() return value instead of chaining raw .pipe() calls with no error handling.
- Reserve worker_threads and the libuv threadpool for genuinely CPU-bound work (crypto, compression, image processing); keep I/O-bound work on the main event loop with async APIs.
- Design REST/GraphQL APIs around idempotency keys, structured error middleware, cursor-based pagination, and rate limiting from day one, not as a later retrofit.
- Scale horizontally with the cluster module or PM2 behind a load balancer, and always implement graceful shutdown so rolling deploys never drop in-flight requests.
Step-by-Step Study Plan
Follow this sequential roadmap designed to take you from core foundations to advanced architecture and mock interviews.
libuv Internals & Non-Blocking I/O Mastery
The six event loop phases, process.nextTick vs Promise microtasks vs setImmediate/setTimeout, and how the libuv threadpool handles fs/crypto/dns work.
- •Trace the exact execution order of a script mixing setTimeout, setImmediate, process.nextTick, and Promise.then.
- •Explain what blocks the event loop and how to measure event loop lag with perf_hooks.monitorEventLoopDelay.
- •Understand UV_THREADPOOL_SIZE and which core APIs (fs, crypto.pbkdf2, dns.lookup, zlib) actually use the libuv threadpool.
- •Rebuild the event loop diagram from memory: timers -> pending callbacks -> poll -> check -> close callbacks.
- •Profile a toy Express app with clinic.js or --prof to spot synchronous bottlenecks.
Backpressure-Safe Streams, Cluster & Worker Threads
Readable/Writable/Transform stream mechanics, backpressure signaling, the cluster module's shared-socket model, and worker_threads with SharedArrayBuffer.
- •Implement a Transform stream and wire it through stream.pipeline() with correct error propagation.
- •Explain how cluster.fork() workers share a listening socket and how connections get distributed across them.
- •Offload a CPU-bound task (hashing, image resize, Fibonacci-style computation) to a worker_threads pool without blocking the main thread.
- •Never call worker.postMessage in a hot loop without batching; measure serialization overhead.
- •Benchmark highWaterMark tuning on a real file-processing pipeline and observe the 'drain' event firing.
REST/GraphQL Hardening, Process Management & Zero-Downtime Deploys
Middleware pipelines, authentication, rate limiting, GraphQL N+1 mitigation with DataLoader, PM2 cluster mode, and graceful shutdown under SIGTERM.
- •Design an Express or Fastify middleware chain with centralized error handling and input validation.
- •Implement graceful shutdown that drains in-flight requests, closes DB pools, and force-exits after a timeout.
- •Explain sticky sessions for WebSocket-heavy services and health-check based rolling deploys behind PM2 or Kubernetes.
- •Run mock system-design drills for 'design a rate limiter' and 'scale a webhook ingestion service to 10k RPS'.
- •Write out your own graceful shutdown handler from scratch without looking at a reference implementation.
1. The libuv Event Loop: Phases, Microtasks & Non-Blocking I/O
Node.js is single-threaded for your JavaScript, but it delegates I/O to libuv, which cycles through a fixed sequence of phases. Interviewers use this topic to separate candidates who memorized 'Node is async' from those who understand exactly when each callback fires.
Executes setTimeout/setInterval callbacks whose threshold has elapsed, ordered by scheduled expiry, not by insertion order.
Retrieves new I/O events from the OS (epoll on Linux, kqueue on macOS, IOCP on Windows) and executes their callbacks; the loop can block here waiting for I/O if no timers or setImmediate calls are pending.
Runs immediately after the poll phase completes for the current iteration, which is why setImmediate fires before setTimeout(fn, 0) when scheduled inside an I/O callback.
process.nextTick() and resolved Promise callbacks are NOT a loop phase; they drain completely (nextTick queue first, then the Promise microtask queue) after every callback and between every phase transition.
One tick of the loop; microtasks (nextTick, then Promises) fully drain between each phase and after each individual callback.
console.log('start');

  setTimeout(() => console.log('timeout'), 0);

  setImmediate(() => console.log('immediate'));

  process.nextTick(() => console.log('nextTick'));

  Promise.resolve().then(() => console.log('promise'));

  console.log('end');

  // Deterministic part of the output:
  // start
  // end
  // nextTick   <- microtask queue #1 always drains first
  // promise    <- microtask queue #2 drains next
  // Then either 'timeout' or 'immediate' first (order is NOT guaranteed
  // in the main module), but inside an I/O callback 'immediate' ALWAYS
// fires before a 0ms 'timeout' because Check runs right after Poll.- When asked 'what blocks the event loop', give concrete examples: synchronous JSON.parse on huge payloads, unbounded regex backtracking, and crypto.pbkdf2Sync in a request handler.
- Mention perf_hooks.monitorEventLoopDelay() as the production tool for measuring event loop lag, not just anecdotal 'the server feels slow'.
- Assuming setTimeout(fn, 0) always fires before setImmediate — the order is only guaranteed inside an I/O callback, not in the top-level module.
- Forgetting that a recursive process.nextTick() call can starve the event loop entirely, since the nextTick queue must fully empty before the loop proceeds.
2. Streams & Backpressure: Readable, Writable & Transform
Streams are Node's answer to processing data too large to fit in memory, but they're also one of the most common places production incidents happen when backpressure is ignored.
A Readable stream starts paused; attaching a 'data' listener or calling .pipe()/.resume() switches it to flowing mode, where chunks are pushed as fast as they're produced.
writable.write(chunk) returns false once internal buffered data exceeds highWaterMark; well-behaved producers pause until the stream emits 'drain'.
pipeline() automatically forwards errors, destroys all streams on failure, and calls a completion callback — raw .pipe() chains leak file descriptors on unhandled errors.
A Duplex stream where output is computed from input (e.g. gzip, CSV parsing); _transform(chunk, enc, callback) must call callback exactly once per chunk to respect flow control.
const { pipeline, Transform } = require('node:stream');
  const fs = require('node:fs');
  const zlib = require('node:zlib');

  class UpperCaseTransform extends Transform {
    _transform(chunk, encoding, callback) {
      // callback() signals "ready for the next chunk" — this is the
      // backpressure contract: never call push() after an unhandled error,
      // and never call callback() more than once per chunk.
      this.push(chunk.toString().toUpperCase());
      callback();
    }
  }

  pipeline(
    fs.createReadStream('input.txt'),
    new UpperCaseTransform(),
    zlib.createGzip(),
    fs.createWriteStream('output.txt.gz'),
    (err) => {
      if (err) {
        console.error('Pipeline failed:', err);
        process.exitCode = 1;
      } else {
        console.log('Pipeline succeeded — backpressure handled end-to-end');
      }
    }
);- In interviews, define backpressure precisely: it's the mechanism preventing a fast producer from overwhelming a slow consumer's memory buffer.
- Bring up object mode streams when discussing processing structured records (e.g. parsed JSON rows) instead of raw Buffers/strings.
- Ignoring the boolean return value of writable.write() and continuing to write anyway, causing unbounded memory growth under load.
- Chaining readable.pipe(transform).pipe(writable) without any 'error' listeners, so a mid-pipeline error is silently swallowed and the process hangs.
3. Scaling CPU Work: The Cluster Module & Worker Threads
A single Node process runs JavaScript on one thread. Real production systems need two different tools depending on the bottleneck: the cluster module to use all CPU cores for I/O-bound throughput, and worker_threads to offload genuinely CPU-bound computation.
A primary process forks N worker processes (typically os.cpus().length); on Linux/macOS the OS load-balances new connections across workers sharing the same listening socket (round-robin on most platforms via SCHED_RR).
Unlike cluster's separate processes, worker_threads run in the same process with isolated V8 heaps, communicating via structured-clone message passing or shared memory through SharedArrayBuffer + Atomics.
fs, crypto.pbkdf2/scrypt, zlib, and dns.lookup already run on libuv's internal threadpool (default size 4, tunable via UV_THREADPOOL_SIZE) — you don't need worker_threads for these.
child_process spawns a fully separate OS process (heavier, isolated memory, own event loop) — better for running untrusted or non-Node executables; worker_threads is lighter-weight for pure computation within the same app.
const { Worker, isMainThread, parentPort, workerData } = require('node:worker_threads');

  function runInWorker(data) {
    return new Promise((resolve, reject) => {
      const worker = new Worker(__filename, { workerData: data });
      worker.once('message', resolve);
      worker.once('error', reject);
      worker.once('exit', (code) => {
        if (code !== 0) reject(new Error('Worker stopped with exit code ' + code));
      });
    });
  }

  if (isMainThread) {
    // Main thread stays free to keep serving other requests while this runs.
    runInWorker({ n: 42 }).then((result) => {
      console.log('CPU-bound result computed off the main event loop:', result);
    });
  } else {
    // Runs on a separate V8 isolate — never blocks the main thread's event loop.
    function fib(n) {
      return n < 2 ? n : fib(n - 1) + fib(n - 2);
    }
    parentPort.postMessage(fib(workerData.n));
}- State the rule of thumb explicitly: I/O-bound work stays on the main thread using async APIs; only genuinely CPU-bound work (image resizing, hashing, large JSON transforms, ML inference) belongs in worker_threads.
- Mention Piscina or a hand-rolled worker pool to avoid the cost of spinning up a new thread per request.
- Reaching for worker_threads to 'fix' a slow database query — that's an I/O latency problem, not a CPU problem, and threads won't help.
- Passing huge objects to postMessage() without realizing the default structured-clone cost; SharedArrayBuffer avoids the copy for numeric data that needs frequent cross-thread access.
4. Production APIs & Horizontal Scaling: Middleware, PM2 & Graceful Shutdown
Shipping an API that survives real traffic means getting the middleware pipeline, error handling, and process lifecycle right — this is where 'it works on my machine' backend code gets separated from production-grade backend code.
Express/Fastify execute middleware in registration order: request parsing -> auth -> rate limiting -> route handler -> centralized error-handling middleware (4-arg signature in Express) last.
Resolving a list field per-parent triggers one query per item; DataLoader batches and caches those lookups within a single request tick, collapsing N queries into 1.
pm2 start app.js -i max forks one process per CPU core (built on the cluster module under the hood) and adds zero-downtime reloads via pm2 reload.
On SIGTERM: stop accepting new connections, let in-flight requests finish, close DB/Redis pools, then exit — with a hard timeout fallback so a stuck deploy doesn't hang forever.
const server = app.listen(port, () => console.log('Listening on ' + port));

  let shuttingDown = false;

  async function gracefulShutdown(signal) {
    if (shuttingDown) return;
    shuttingDown = true;
    console.log(signal + ' received: draining connections');

    server.close(async () => {
      try {
        await dbPool.end();       // close DB connection pool cleanly
        await redisClient.quit(); // close cache connections cleanly
        console.log('Cleanup complete, exiting');
        process.exit(0);
      } catch (err) {
        console.error('Error during shutdown', err);
        process.exit(1);
      }
    });

    // Force-exit if connections don't drain in time (e.g. a stuck socket)
    setTimeout(() => process.exit(1), 10_000).unref();
  }

  process.on('SIGTERM', () => gracefulShutdown('SIGTERM'));
process.on('SIGINT', () => gracefulShutdown('SIGINT'));- Bring up sticky sessions explicitly when discussing WebSocket or Socket.IO services behind a cluster/PM2/load balancer, since a client must keep hitting the same worker for stateful connections.
- Mention readiness vs liveness probes: readiness should fail fast during shutdown so the load balancer stops routing new traffic before the process actually exits.
- Calling process.exit() immediately on SIGTERM without draining in-flight requests, causing dropped responses on every rolling deploy.
- Running PM2 cluster mode and a hand-rolled cluster.fork() setup at the same time, silently doubling the number of worker processes per core.
Scaling a Fintech Webhook Ingestion Service From 200 to 12,000 RPS
A payments team's Node.js/Express service ingested webhook events from card processors, verifying an HMAC signature and writing each event to Postgres before acknowledging. During a partner's Black Friday traffic spike, the service fell badly behind, timing out webhooks and triggering costly retry storms from the upstream processor.
- 1Profiled the service under load with clinic.js and perf_hooks.monitorEventLoopDelay, finding synchronous HMAC verification (crypto.createHmac used correctly, but a heavy custom JSON schema validator run synchronously) was blocking the event loop for 40-80ms per request.
- 2Moved the CPU-heavy schema validation into a small worker_threads pool sized to available cores, keeping HMAC verification (already fast) on the main thread.
- 3Replaced ad-hoc .pipe() chains used for archiving raw payloads to S3 with stream.pipeline(), fixing a slow file-descriptor leak that had been causing periodic restarts.
- 4Deployed the service under PM2 in cluster mode across all 8 cores per node, with a graceful shutdown handler draining in-flight requests on SIGTERM before deploys.
- 5Added a Redis-backed token-bucket rate limiter and pushed downstream database writes through a BullMQ queue so ingestion accepted webhooks even when Postgres was briefly saturated.
- 6Added readiness probes that failed fast during both startup and shutdown so the load balancer never routed traffic to a pod that wasn't truly ready.
Top Must-Know Interview Questions & Model Answers
Q1: Walk through the six phases of the Node.js event loop in order.
- •Timers phase runs expired setTimeout/setInterval callbacks ordered by expiry time, not insertion order.
- •Poll phase is where the loop can block waiting for new I/O if nothing else is scheduled; it also runs I/O callbacks that have already fired.
- •Check phase runs setImmediate callbacks immediately after poll finishes for that iteration; close callbacks phase runs handlers like socket.on('close') last.
Q2: What is the difference between process.nextTick(), Promise microtasks, and setImmediate()?
- •The nextTick queue is processed before the Promise microtask queue whenever both have pending callbacks.
- •Microtasks run after every single callback completes, not just between phases — a recursive nextTick call can starve the entire event loop.
- •setImmediate is guaranteed to run before a 0ms setTimeout only when both are scheduled from within an I/O callback.
Q3: Why is Node.js described as 'single-threaded' when it clearly uses multiple threads under the hood?
- •Network I/O (sockets, HTTP) uses OS-level async mechanisms (epoll/kqueue/IOCP) and doesn't need the threadpool at all.
- •fs operations, crypto.pbkdf2/scrypt, zlib compression, and dns.lookup are dispatched to the libuv threadpool because the underlying syscalls are blocking.
- •V8 itself also runs GC and JIT compilation on auxiliary threads, separate from your JS execution thread.
Q4: What are common causes of event loop blocking in a production API, and how would you detect it?
- •A single request doing JSON.parse on a 50MB payload synchronously stalls every other concurrent request until it finishes.
- •Catastrophic regex backtracking (ReDoS) on user input is a classic blocking bug that also doubles as a security vulnerability.
- •Tools like clinic.js doctor or 0x flamegraphs pinpoint exactly which function is holding the thread.
Q5: What is the libuv threadpool and how do you tune it?
- •fs (excluding a few that use native async APIs), DNS lookups via dns.lookup, and some crypto/zlib functions are dispatched here.
- •If you run many concurrent password hashes (bcrypt/scrypt) with only 4 threadpool slots, requests queue up waiting for a free thread even though your event loop itself is idle.
- •UV_THREADPOOL_SIZE must be set before the process starts (it's read once at startup) and applies process-wide, not per-request.
Q6: What is the difference between a microtask queue and a macrotask (event loop phase) queue?
- •Because microtasks fully drain before the next macrotask, an infinite chain of Promise.then() calls will starve timers and I/O indefinitely.
- •This distinction is why 'async/await heavy' code can still starve the event loop if each awaited function schedules more microtasks synchronously without ever yielding to I/O.
Q7: Explain the difference between paused (non-flowing) and flowing mode in a Readable stream.
- •Every Readable stream starts in paused mode; switching to flowing and back to paused is possible but rarely done manually in application code.
- •Flowing mode without any backpressure-aware consumer is exactly how memory blows up when reading a huge file faster than it can be processed downstream.
Q8: What exactly is backpressure in Node.js streams, and how is it signaled?
- •Ignoring the false return value and continuing to call write() anyway causes internal buffers to grow unbounded, eventually crashing the process with an out-of-memory error.
- •pipe() and pipeline() handle this automatically by pausing the source stream until 'drain' fires on the destination.
Q9: What's the difference between a Duplex stream and a Transform stream?
- •Transform streams implement _transform(chunk, encoding, callback) instead of separate _read/_write, and can also implement _flush() for any trailing output.
- •A net.Socket is the canonical Duplex example: what you read from it has nothing to do with what you write to it.
Q10: Why should you prefer stream.pipeline() over chaining multiple .pipe() calls?
- •With raw .pipe(), an error on any stream except the last one is not automatically propagated and must be manually listened for on each stream.
- •pipeline() (and its Promise-based util.promisify or stream/promises variant) is now the documented, recommended way to compose stream chains since Node 10.
Q11: How does tuning highWaterMark affect a stream's memory and throughput trade-off?
- •Default is 16KB for byte streams and 16 objects for object-mode streams.
- •For large-file processing pipelines under memory pressure (e.g. containers with tight limits), lowering highWaterMark trades some throughput for predictable memory ceilings.
Q12: What is object mode in Node.js streams and when would you use it?
- •Enabled by passing { objectMode: true } to the stream constructor; highWaterMark then counts objects instead of bytes.
- •Common in ETL-style pipelines: a Transform stream parses raw CSV bytes into row objects, and downstream Transforms operate purely on those objects.
Q13: Explain the architecture of the Node.js cluster module.
- •On most platforms the OS/kernel or Node's internal round-robin scheduler decides which worker handles each new connection.
- •Workers are separate OS processes with independent memory and event loops — a crash in one worker doesn't take down the others.
- •The primary can listen for 'exit' events and re-fork a replacement worker for self-healing.
Q14: When would you choose worker_threads over the cluster module, or vice versa?
- •cluster workers are full processes (heavier, isolated memory, separate DB connection pools per worker) — great for horizontal request throughput.
- •worker_threads share the process but have isolated V8 heaps, communicating via message passing or SharedArrayBuffer — ideal for a single hot CPU-bound function.
- •You can combine both: cluster for request distribution across cores, and a worker_threads pool inside each cluster worker for occasional heavy computation.
Q15: How do worker_threads share memory efficiently, and what problem does SharedArrayBuffer solve?
- •Structured cloning is fine for small messages but becomes a bottleneck when passing large buffers or arrays repeatedly.
- •Atomics.wait/notify provide low-level synchronization primitives so multiple threads can safely read/write shared memory without races.
Q16: How does the cluster module distribute incoming connections across workers?
- •Round-robin can be switched off in favor of SCHED_NONE, letting the OS decide, which sometimes causes uneven load in practice.
- •Long-lived connections (like WebSockets) complicate this model since a worker restart drops that worker's active connections.
Q17: How would you achieve a zero-downtime restart of a clustered Node.js application?
- •The primary listens for a signal, forks a replacement worker, waits for the 'listening' event, then calls worker.disconnect() on one old worker at a time.
- •Each outgoing worker should still finish in-flight requests via graceful shutdown before exiting.
Q18: What's the difference between child_process, cluster, and worker_threads?
- •child_process.spawn/exec/fork all create OS-level processes with their own memory and event loop; fork() specifically is for spawning other Node scripts with an IPC channel.
- •worker_threads is the lightest-weight option since it avoids full process startup cost, making it better suited to short-lived CPU-bound tasks.
Q19: Design the middleware pipeline for a production Express or Fastify API. What order do things run in?
- •Express executes middleware strictly in registration order; an error-handling middleware must have exactly 4 parameters (err, req, res, next) to be recognized as such.
- •Fastify uses a similar hooks model (onRequest, preHandler, etc.) but validates/serializes against JSON Schema at each route for better performance.
Q20: How do you solve the N+1 query problem in a GraphQL API?
- •Without DataLoader, resolving a 'friends' field for 100 users triggers 100 separate database round-trips, one per user.
- •DataLoader keys its cache per-request (a fresh instance per GraphQL request) to avoid stale cross-request data leaking between users.
Q21: What strategies exist for API versioning, and what are the trade-offs?
- •URI versioning is the most discoverable and cache-friendly but clutters the URL space and encourages long-lived old versions.
- •Header-based versioning keeps URLs clean but is harder to test manually and less visible to API consumers browsing docs.
Q22: How would you implement a rate limiter middleware for a Node.js API?
- •In-memory rate limiting only works correctly on a single instance; behind a cluster or multiple horizontally scaled pods it must be centralized in Redis or similar.
- •Token bucket allows short bursts up to the bucket size while enforcing a steady average rate, which fits bursty client traffic better than a strict fixed window.
Q23: What performance advantages does Fastify offer over Express, and when does it matter?
- •Schema-based response serialization in Fastify is compiled ahead of time into a fast JSON stringify function instead of relying on the generic JSON.stringify.
- •For most CRUD APIs with modest traffic the difference is immaterial; it becomes relevant at very high RPS or when serialization dominates request latency.
Q24: How would you design JWT authentication with refresh token rotation for an API?
- •Rotating refresh tokens means reusing an already-used refresh token is a strong signal of theft, letting you revoke the whole session family.
- •Access tokens should never be stored in localStorage in a way exposed to XSS; HttpOnly, SameSite cookies mitigate token exfiltration.
Q25: How do you make a POST endpoint idempotent to safely handle client retries?
- •This is critical for payment and order-creation endpoints where a network retry after a timeout must never double-charge a customer.
- •The key should be scoped per-user/per-resource to avoid collisions between unrelated clients.
Q26: What's the difference between PM2 cluster mode and manually using the Node cluster module?
- •pm2 start app.js -i max forks one worker per CPU core automatically, equivalent to manually calling cluster.fork() os.cpus().length times.
- •PM2 additionally exposes metrics (CPU/memory per worker) and a process list, which a hand-rolled cluster setup doesn't give you for free.
Q27: Walk through a correct graceful shutdown sequence for a Node.js service running under Kubernetes.
- •Kubernetes sends SIGTERM and waits for terminationGracePeriodSeconds (default 30s) before sending SIGKILL, so your drain timeout must be safely shorter than that.
- •Failing readiness before closing the server gives the load balancer/kube-proxy time to stop routing new traffic to the pod before it actually stops accepting connections.
Q28: How do you handle WebSocket connections in a horizontally scaled, load-balanced Node.js deployment?
- •Sticky sessions are simpler but reduce the effectiveness of load balancing and complicate rolling deploys, since restarting one instance disconnects all its sockets.
- •A Redis (or similar) pub/sub backplane decouples 'which instance holds the socket' from 'which instance needs to send a message', enabling true stateless horizontal scaling.
Q29: What's the difference between horizontal and vertical scaling for a Node.js API, and why is horizontal generally preferred?
- •Because a single Node process is bound mostly by one CPU core for JS execution, vertical scaling past a certain point yields diminishing returns unless paired with cluster/worker_threads to use the extra cores.
- •Horizontal scaling also enables rolling deploys and graceful degradation — losing one of ten instances is far less impactful than losing your only vertically-scaled instance.
Q30: What should a Node.js service's health check endpoints actually verify?
- •Conflating the two causes cascading failures: if liveness checks the database and the DB has a blip, Kubernetes kills and restarts otherwise-healthy pods.
- •Readiness should fail during startup (before DB pool is warmed) and during graceful shutdown (once draining begins), so traffic is only ever routed to pods truly able to serve it.
Mistakes That Sink Otherwise Strong Candidates
Why it happens: Operations like JSON.parse on huge payloads, *Sync fs/crypto calls, or unbounded regex feel 'simple' and their cost is invisible until concurrent load reveals it.
The fix: Profile with perf_hooks.monitorEventLoopDelay or clinic.js, and move genuinely CPU-bound work to a worker_threads pool while keeping I/O on async APIs.
Why it happens: write() still 'works' when it returns false, so the bug only manifests as slow, hard-to-reproduce memory growth under real production load.
The fix: Check the boolean return value and pause the producer until 'drain' fires, or simply use stream.pipeline() which manages this automatically.
Why it happens: Happy-path testing rarely triggers stream errors, so the missing error handling goes unnoticed until a real malformed file or network blip hangs the process.
The fix: Use stream.pipeline() (or its Promise-based variant), which forwards errors from any stream and guarantees proper cleanup on failure.
Why it happens: Threads feel like a generic 'go faster' hammer, but a slow query is an I/O latency problem, and moving it to a worker thread doesn't reduce the wait.
The fix: Diagnose whether the bottleneck is CPU-bound (worker_threads helps) or I/O-bound (needs query optimization, caching, or connection pool tuning instead).
Why it happens: The threadpool is invisible in code, so teams don't realize concurrent bcrypt/scrypt hashing or heavy file I/O is queuing behind only 4 background threads.
The fix: Set UV_THREADPOOL_SIZE (e.g. to the core count) before process startup, and benchmark to confirm the change actually relieves the bottleneck.
Why it happens: Individual try/catch blocks feel like sufficient coverage, but a missed .catch() on a fire-and-forget Promise crashes silently or leaves the process in an undefined state.
The fix: Register process-level handlers to log the error with full context and perform a controlled shutdown/restart rather than letting the process hang or crash uncontrolled.
Why it happens: It looks like the 'simple' way to handle a shutdown signal, and it works fine locally where there's no real traffic to interrupt.
The fix: Implement a graceful shutdown sequence: stop accepting new connections, let existing requests finish, close DB/cache pools, then exit, backed by a hard timeout.
Why it happens: A team adopts PM2 for operational tooling but forgets the app already forks its own workers internally, silently multiplying the process count per core.
The fix: Pick exactly one layer to own process forking — either PM2's -i max flag or your own cluster module code, never both.
Why it happens: In-memory counters are the fastest thing to prototype and pass local testing on a single instance.
The fix: Back the rate limiter with Redis (or another shared store) so limits are enforced consistently across every instance behind the load balancer.
Why it happens: REST endpoints genuinely are stateless, but WebSocket/Socket.IO connections are inherently long-lived and tied to whichever instance accepted them.
The fix: Either configure sticky sessions at the load balancer for WebSocket traffic, or adopt a Redis pub/sub backplane so any instance can reach any connected client.
Quick-Reference Cheat Sheet
Recommended Practice Quizzes on QuizCluster
Test your retention and prepare for timed live coding and MCQ technical screening rounds:
JavaScript & TypeScript
Sharpen the async/await, closures, and type-system fundamentals that underpin every Node.js API and stream you'll build.
OS, Concurrency & Thread Safety
Practice thread pools, race conditions, and locking concepts that map directly onto cluster and worker_threads design decisions.
Frequently Asked Questions
Is Node.js really single-threaded, and does that matter for interviews?
Your JavaScript executes on a single thread, but libuv runs a background threadpool for blocking OS operations, and you can spin up worker_threads or cluster workers for true parallelism. Interviewers care most that you can precisely explain what runs where.
Should I prepare with Express or Fastify for backend interviews?
Express is still the most commonly assumed framework in interviews and take-home tests, so know its middleware model cold. Fastify knowledge is a strong bonus signal for performance-focused roles, but it's rarely a hard requirement.
How deep do I need to go on streams if I mostly build REST APIs?
Deep enough to explain backpressure and describe a Transform stream from memory — streams questions are a favorite way to test whether you understand memory and flow control, even if you rarely hand-write custom streams day to day.
If my team already deploys on Kubernetes, do I still need to know PM2?
Know the concepts PM2 encodes (cluster mode, zero-downtime reload, health-based restarts) even if Kubernetes handles orchestration in production — interviewers use PM2 as a concrete, well-known vocabulary for those same ideas.